Cohere Rerank 5: Select Relevant Passages for Shorter RAG Context
The retriever found the right document, but the model still gets pages of text for a one-line question. How does Rerank 5 pass along only the passages that matter?
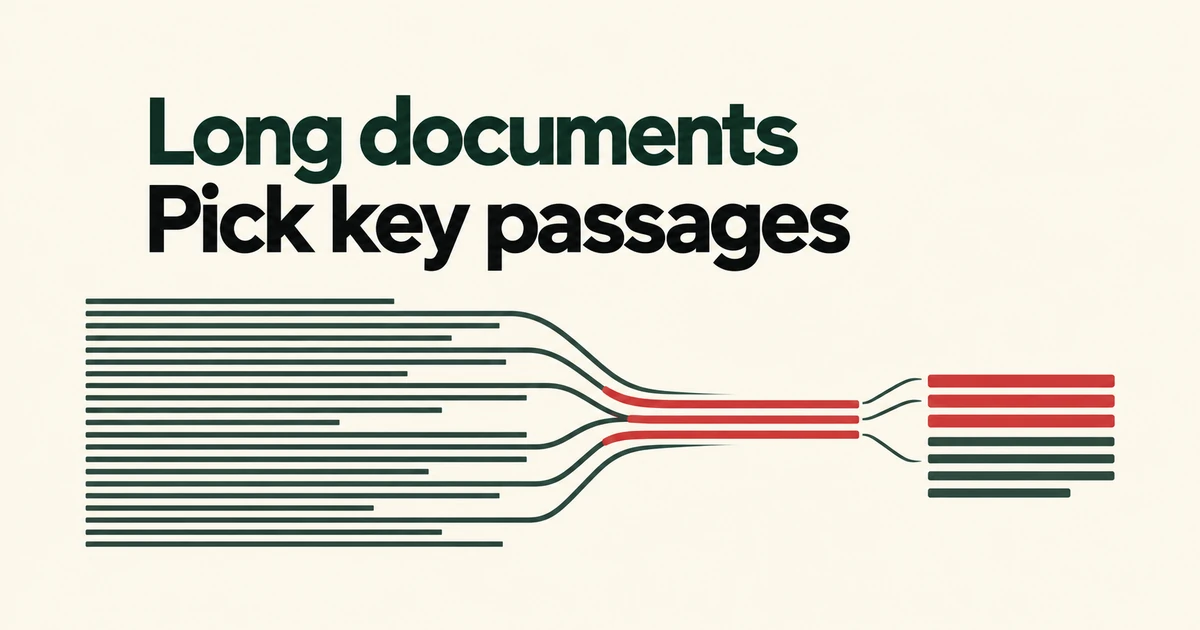
- Context Focus can identify the passages an LLM needs within long retrieved documents.
- Enable the option and use the returned spans in the next model request; switching rerankers alone does neither.
- Full-document summaries and structured material may need context that passage selection would omit.
Choose the document, then choose the evidence inside it
Cohere’s October 21 announcement introduces Context Focus as an optional passage-selection capability in Rerank 5. A call can return document relevance scores and relevant spans within those documents.
Ranking decides which sources come first. Passage selection decides which parts of those sources reach the language model. A system forwarding entire highly ranked documents can therefore change its context length without changing the underlying search index.
The release notes say upgrading a reranker does not require re-embedding or re-indexing the corpus. Context Focus is off by default, however, so upgrading and enabling passage selection are separate changes.
The result points into the original text
The model guide enables the feature through relevant_spans, with mode set to enabled. Returned spans carry start and end character offsets plus a score.
| Field | Purpose |
|---|---|
| threshold | Sets the passage-selection cutoff; higher values remove more text. |
| max_spans | Caps the number of spans returned per document. |
| start / end | Locate the passage in the submitted text. |
| top_n | Limits the number of ranked documents returned. |
The v2 API reference gives top_n a document-level role. It should not be confused with the per-document span cap. If no passage clears the threshold, that result can omit relevant_spans.
Applications must retrieve text at the returned offsets and build the downstream context. They also need a policy for absent spans, such as retaining the source or seeking other evidence. Enabling an API option alone does not alter the next LLM call.
Model choice and deployment choice have different prices
Cohere positions rerank-v5.0-pro for ranking quality on complex queries and specialist documents, and rerank-v5.0-fast for latency and throughput. Both support Context Focus.
The October 21 announcement lists API rates of $0.05 per million tokens for Pro and $0.02 for Fast. Those are reranking prices; a downstream model’s answer-generation charges are separate.
Model Vault pricing uses dedicated-instance rates with hourly or commitment-based billing. A model’s token-based API price and its dedicated deployment cost are different quantities.
Targeted questions are the clearest fit
Cohere’s model documentation identifies targeted queries as the best fit. Broad tasks such as summarization need the full document, while tables, forms and code do not divide into passages as neatly as prose.
The company also describes calibrated document relevance scores. These estimate whether a document is useful to the query. They do not measure the correctness of an answer subsequently generated from selected parts of that document.
A practical comparison is to run the same questions with full source context and selected passages. Check whether the shorter input retains the conditions and exceptions needed for the answer. Token reduction and evidence retention answer different questions.
FAQ
Does changing the model name automatically reduce context?
No. Enable Context Focus and use its output when constructing the LLM request.
Does Context Focus write a new summary?
Its span output identifies positions in the original document, with scores. The application can extract that text.
The consequential change is what the next LLM call receives. Connect passage selection to that request, then compare the smaller input with the evidence the answer still needs.